Nearly all speech-to-text systems work in a single pass. Audio goes in, text comes out, and whatever the model misheard stays misheard. A group of researchers has now built a workflow that allows a transcript to be corrected interactively while the conversation is still happening.
What's new. Zixuan Jiang, Yanqiao Zhu, Peng Wang and colleagues at Shanghai Jiao Tong University, Zhejiang University, Fudan University and Xiaoice, a spinoff from Microsoft, combined an automatic speech recognition engine with a large language model that looks for and repairs transcription errors at each conversational turn. They call the system Agentic ASR.
Key insight. The common fix for transcription errors is to put an LLM behind the speech model and have it rewrite the output. The trouble is that a correction request simply gets appended to what is already there, and asking a model to regenerate a transcript wholesale invites new mistakes, particularly around unusual words. A name like Megan can easily come back as Morgan. Splitting the job into three stages instead, locating the error, working out what the speaker meant, then applying the change, produces better revisions. The model stops behaving like a rewriter and starts behaving like an editor.
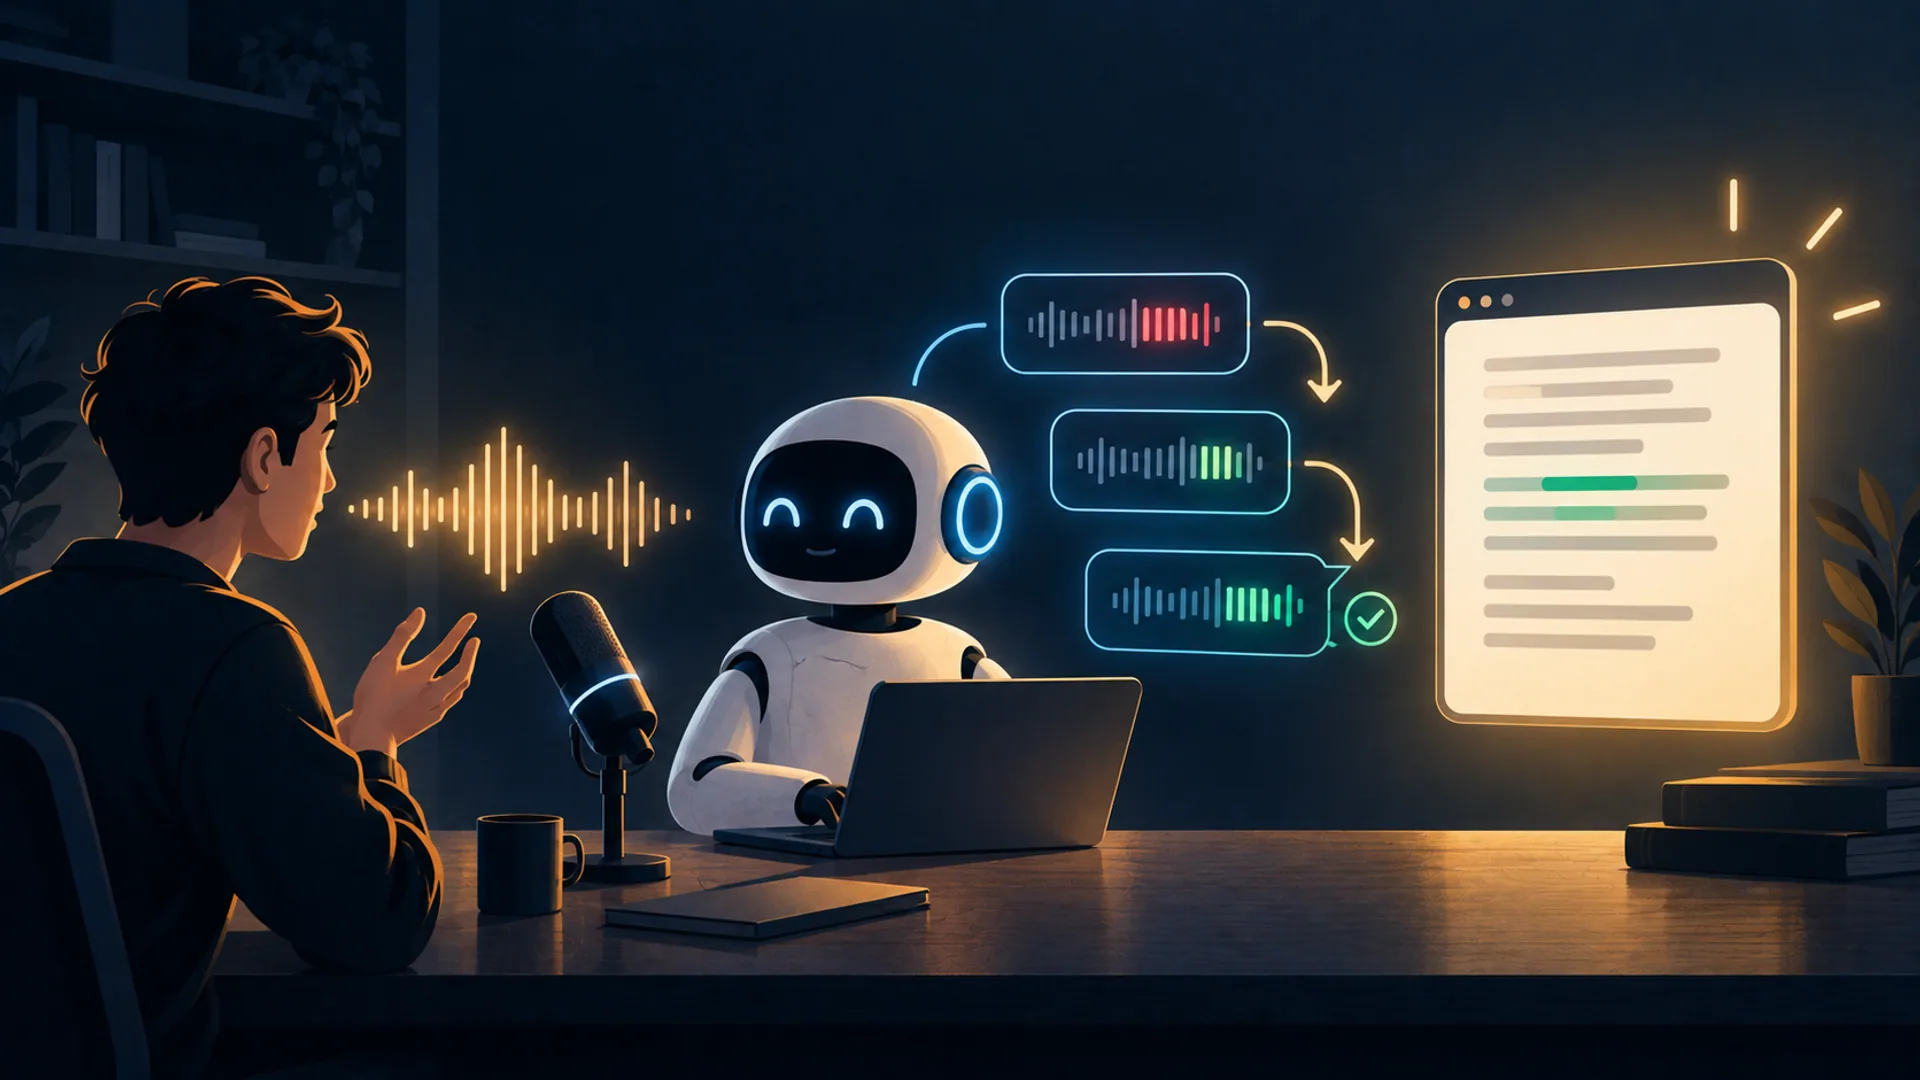
How it works. Agentic ASR treats transcription as something refined over several turns, with the user dictating and then either confirming or amending what appears.
- Qwen3-ASR-1.7B produces an initial transcription of the incoming speech, and Qwen3-32B refines it against the text produced so far.
- The LLM sorts each new utterance into one of three intents: confirmation, where the user accepts the current state; new input, where the user is adding to the transcript; or correction, where the user wants something altered.
- Confirmation and new input leave earlier text untouched. A correction triggers the full sequence: the model identifies the span to change, interprets the instruction, and edits accordingly.
Results. The team tested the workflow on multilingual speech benchmarks. Since none of those benchmarks contain examples of users correcting output, the corrections were simulated with an LLM and a text-to-speech engine. The authors also introduced a metric, S²ER, measuring the share of transcription attempts that fail to preserve the speaker's intended meaning, with Qwen3-32B judging against a ground-truth transcript. They compared performance at zero turns, equivalent to Qwen3-ASR-1.7B transcribing unaided, against ten turns of interaction. Semantic errors dropped on every benchmark, with most of the gain arriving early.
| Benchmark | S²ER at turn 0 | S²ER after 10 turns | Word-level metric |
|---|---|---|---|
| GigaSpeech | 21.5% | 3.5% | WER 11.9% to 10.4% |
| AISHELL-NER | 19.9% | 2.0% | Named-entity error rate 2.4% to 1.2% |
| ASRU2019 (English and Mandarin mixed) | 28.6% | 1.4% | Mixed error rate 6.6% to 3.3% |
On AISHELL-NER, a benchmark dense with names and dates, semantic errors fell by an order of magnitude while the word-level score barely moved.
Why it matters. Systems that take voice input generally need to grasp intent rather than capture every syllable, and Agentic ASR handles that well while still tightening accuracy where individual words genuinely matter. As voice-driven interfaces spread, robustness of this kind becomes harder to treat as optional. The decomposition itself may travel further than speech: find the error, establish what the person wanted, make the change, is a plausible template for editing documents, reviewing code and iterating on designs.